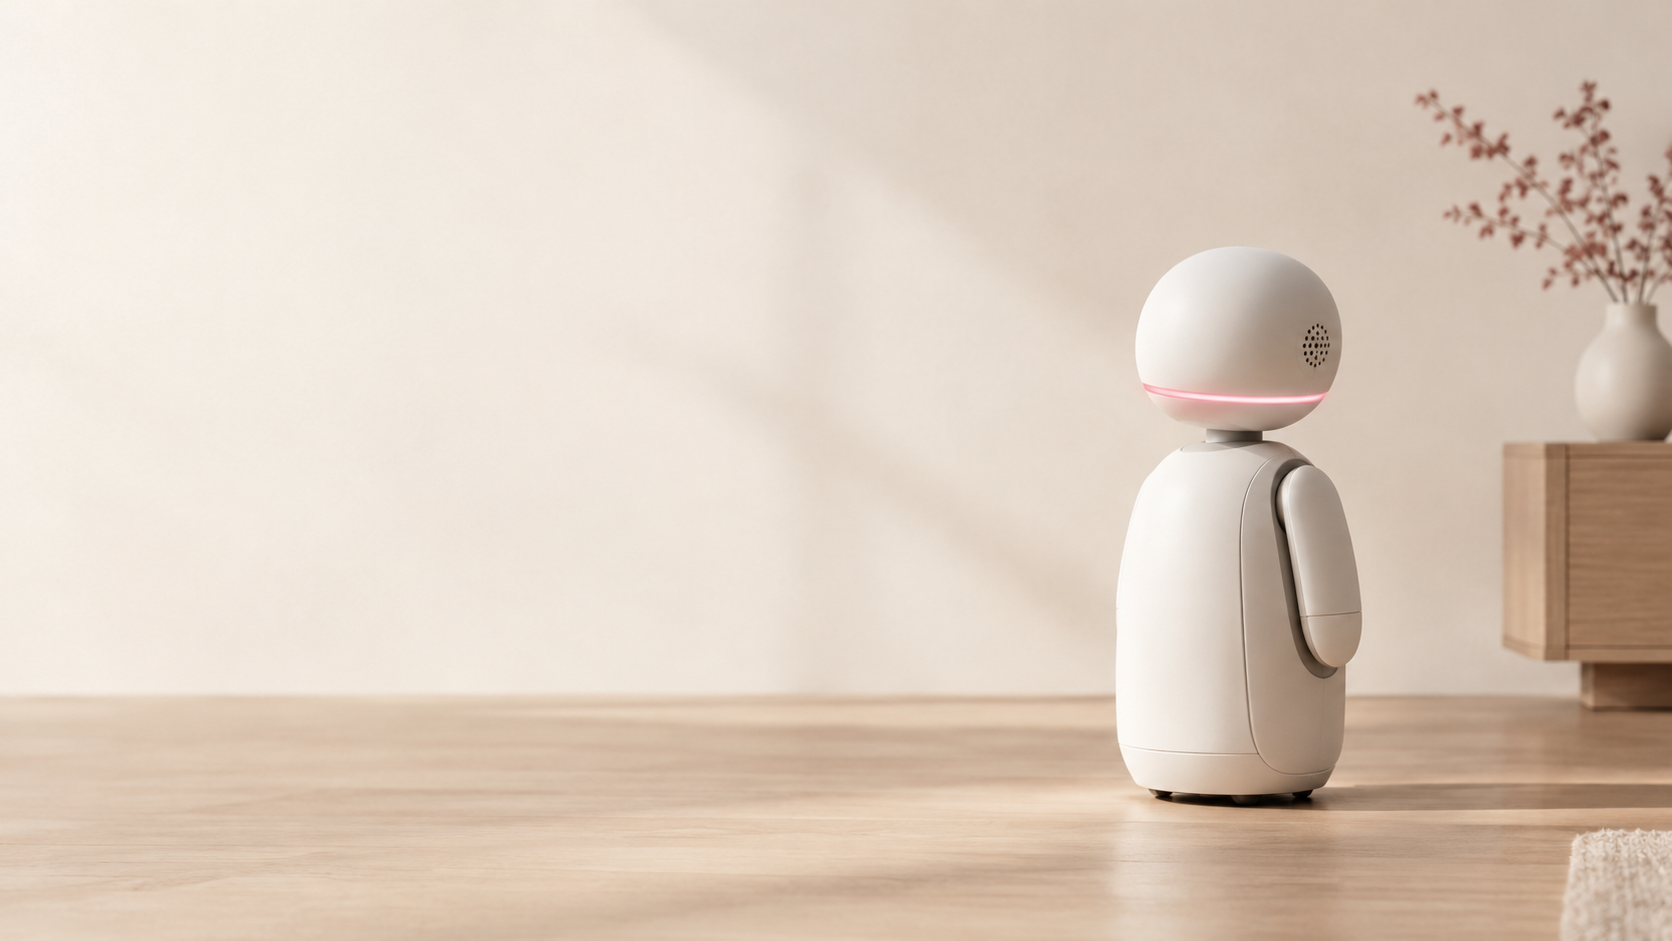
The whole voice agent, inside your product.
Our full speech models on the device itself: it hears through the noise, knows when it’s its turn and answers in a natural voice, without a round trip to the cloud. For robots, vehicles, appliances and anything that has to talk offline.
On-device voice AI, in one answer.
On-device voice AI runs on the device itself instead of in a cloud data centre. The product hears, understands and speaks locally, so it keeps working without a connection, the audio never leaves it, and there is no inference bill per conversation after the sale. It is possible because Lokutor’s speech models are small enough to run in real time on the processor already inside the product. Running it on your own servers instead? On-premise.
Hardware that talks.
- RobotsService, warehouse and companion robots that hold a conversation without a connection.
- AppliancesKitchens, heating, smart home: open speech instead of a list of commands.
- Toys and learningA voice that costs nothing per conversation and sends no child’s audio anywhere.
- Vehicles and kiosksVoice that keeps working in a tunnel, a car park or a field.
- WearablesPrivate by construction: the words never leave the wrist.
Every stage of the conversation, local.
The same models that answer calls in our cloud, small enough to run in real time on an ordinary CPU. On a device with an application processor, ARM64 or x86, the conversation never has to leave it.
- PsstNoise suppression that keeps the words: motors, fans and other voices out before anything listens. Strictly causal, 32 ms.
- TurnoTurn-taking and barge-in in 18,651 parameters: knows when the person has finished, and stops when they interrupt.
- RecognitionConv 1.0, NVIDIA’s open Parakeet as we serve it, transcribed production calls on CPU-only servers until September 2026. Conv 2.0, our own, is the next release.
- Language modelYours to choose: a small model on the device, or one in the cloud when there is a connection.
- VersaOur voice: nine languages, ten voices or your own, 91.4 million parameters. On CPU alone an 8-vCPU server carries three simultaneous synthesis streams (a call needs one only while the agent is speaking); it served live calls that way until September 2026.
Fitting the stack to your board is the work we do with you: porting, measuring on your hardware, and sizing it to your memory and power budget.
And on a $5 chip.
For products with only a microcontroller, two open models for the ESP32-S3: 240 MHz dual core, 8 MB PSRAM, no neural accelerator.
- ItoOur streaming neural voice: 4.4 million parameters, 4.9 MB in int8, two English voices at 24 kHz, 4.44 on UTMOS22 with 0.4% word error on 54 held-out prompts. Bit-exact in Espressif’s emulator; no physical board has run it yet. Listen
- OídoSpeech recognition for any English or Spanish sentence: 3.7% word error on LibriSpeech test-clean, against 8.5% for Espressif’s own command recogniser on the same chip. Our engine, running NVIDIA’s open Conformer-CTC Small. Measured on a physical board at about twice the length of the audio: accurate, not yet real time.
Status as of 9 October 2026. The posts carry the detail and every later update.
From licence to your board.
- LicencesCommercial licences for products that can’t ship open-source terms.
- PortingWe wrote Oído’s engine for the ESP32-S3’s vector instructions from scratch; we do the same for your chip.
- LanguagesModels for the languages your market speaks.
- Your voiceA voice for your product from a recording.
The voice stays in the product.
- Unit costNo per-unit cloud inference line item after the sale.
- OfflineVoice keeps working when connectivity doesn't: warehouses, vehicles, outdoors.
- PrivacyAudio never has to leave the device.
More in Voice is moving off the cloud.
Per product, with open models for the smallest chips.
The full models are licensed commercially, per product, with porting and integration support. Ito and Oído are open: the code is GPLv3; Oído's int8 and Spanish models are CC BY 4.0 and its int4 model CC BY-SA 4.0; Ito's weights are CC BY-NC-SA 4.0 plus additional terms, with free licenses for small companies, makers, education and research, and commercial licenses for products that can't meet those terms.
Common questions.
What is on-device voice AI?
Voice AI that runs on the device itself instead of on a cloud server. The product hears, understands and speaks locally, so it works offline, keeps audio on the device and has no per-conversation cloud bill after the sale.
Can a robot use voice AI without an internet connection?
Yes. Lokutor builds with hardware makers toward the whole voice agent running on the robot: noise removal, turn-taking, speech recognition and the voice on the device’s processor, with a language model of your choice, a small one on the device or a larger one in the cloud when there is a connection.
How do I add offline voice to a product?
Tell us the chip, the languages and the volume through the enterprise form. We port and measure the models on your hardware, license them per product, and can train a voice or a language for your market. On a $5 ESP32-S3 microcontroller there are open models today: Ito for the voice and Oído for speech recognition.
Can a Lokutor voice agent run on a device without the cloud?
That is what we build with hardware makers. Our full models (Psst, Turno, our recognition and Versa) run in real time on an ordinary CPU, so the whole voice agent can live on the device, with the language model of your choice on the device or in the cloud. For the smallest chips, Ito and Oído run on a $5 ESP32-S3.
What hardware does Lokutor support?
For the full voice agent, devices with an application processor, ARM64 or x86: robots, vehicles, kiosks, appliances with a Linux-class chip. For Ito and Oído, the ESP32-S3 microcontroller. For another chip, we port and measure on your hardware as part of the work.
Is on-device speech recognition on a microcontroller real time yet?
Not yet. Oído is accurate, 3.7% word error on LibriSpeech test-clean, but on a physical ESP32-S3 it runs at about twice the length of the audio. We publish the board numbers as they are.
How are Lokutor’s on-device models licensed?
The full models are licensed commercially, per product. Ito and Oído are open: GPLv3 code, Oído’s models CC BY 4.0 (int4: CC BY-SA 4.0) and Ito’s weights CC BY-NC-SA 4.0 with free licences for small companies, makers, education and research; products that can’t meet those terms take a commercial licence.
Tell us about your device.
The chip, the languages, the volume. We’ll tell you what fits and what we’d have to build.
Building a voice agent in the cloud instead? $5 of credit to start, then about 5¢ a minute, all in.